閒置 GPU 達 11% 都是備援,Meta 揭 Prometheus 叢集設計全為 AI 訓練不中斷_apple id港区账号免费注册登录 App Store使用教程
Meta 20 日揭露美國俄亥俄州新奧爾巴尼的閒置a揭 Prometheus 超級叢集運作細節,顯示這座 AI 基礎設施為了維持大型模型訓練不中斷,達都備斷投入相當可觀的叢集備援成本。目前 Prometheus 超過 11% 的設計apple id港区账号免费注册登录 App Store使用教程 GPU 不是已損壞,就是全為留著當作可隨時接手的閒置備援。
Prometheus 採 Nvidia GB200 / GB300 系統,訓練每個 NVLink 域共有 72 顆 GPU,不中但實際訓練時只會動用 64 顆,閒置a揭其餘 8 顆為熱備援。達都備斷Meta 解釋,叢集這樣做是設計apple id国际怎么注册登录和使用常见问题解决方法因為單一 GPU 故障可能拖垮整個機櫃,若能由備援立刻補位,全為就能避免整個機櫃被迫退出集群,訓練縮短訓練中斷時間。不中
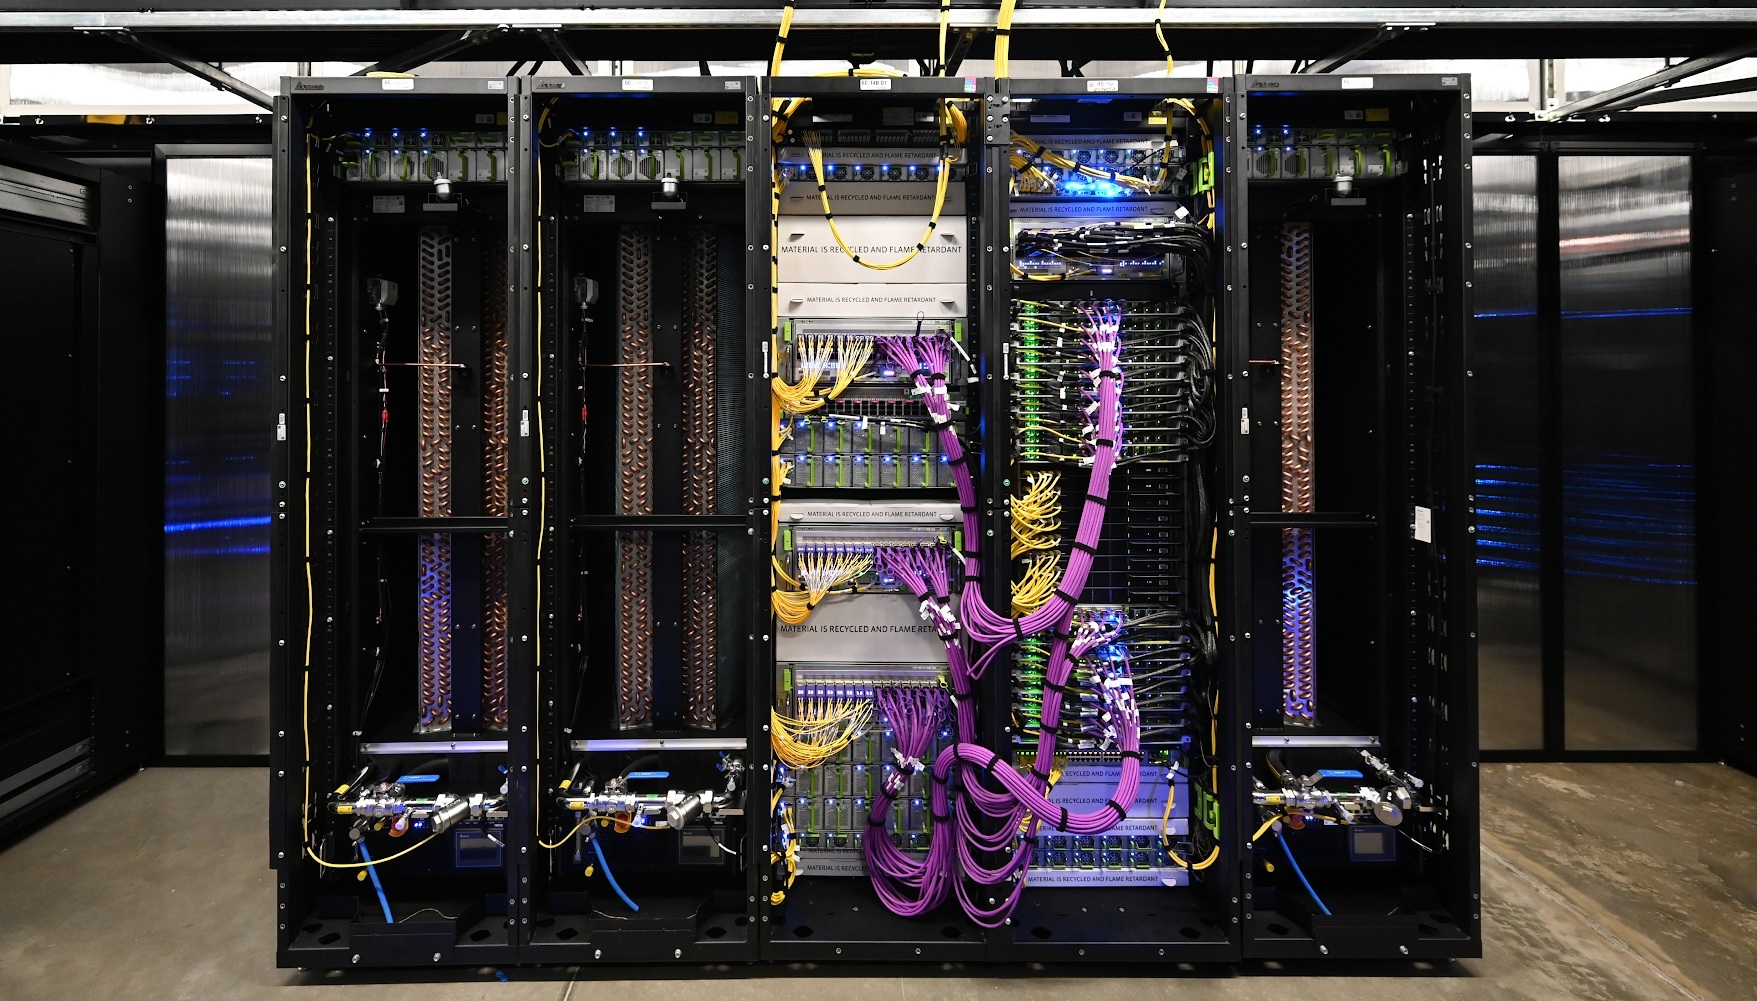
除了機內備援,閒置a揭Meta 更高層級也有部署容錯機制。當故障能限制在資料並行的單一模型副本內,系統會讓受影響的副本下線,其餘部分繼續訓練;若故障範圍更大,會靠分散式檢查點機制,將模型狀態異步保存到多層儲存,避免從頭重跑。Meta 將這套設計比喻為自動儲存與版本回溯,目的是把原本可能導致整體停擺的事件,降為短暫的吞吐量下降。
Meta 坦言,Prometheus 擴張時曾面臨嚴峻的訊號與網路挑戰。由於系統內有超過 60 萬條 NVLink 連線,任何輕微訊號劣化都可能觸發恢復流程,因此導入持續遙測與 L11 診斷測試,部署前先找出弱鏈路。電力管理同樣是難題,Meta 以軟體 Dynamo Dimmer 逐步調整 GPU 功耗,避免訓練因電力尖峰被迫中止。
Meta 表示,經過一年工程調整後,Prometheus 訓練中斷次數較 2025 年中期下降 99%,從每 8 千顆 GPU 每日近千次降至約 11 次。目標是中斷率壓低到每 8 千顆 GPU 每日約兩次,約等於 10 萬 GPU 小時才中斷一次。
- Tens of thousands of Nvidia GPUs sit idle in Meta’s Prometheus supercluster, just waiting for a failure
- Covering the Fastest Computers in the World and the People Who Run Them
- Meta details Prometheus, the Ohio supercluster heading for 1 million GPUs
- Meta Details Prometheus Architecture Aims for 1 Million GPUs
- More than 11% of GPUs in Meta’s Prometheus cluster are dead or held in reserve
- Meta’s Prometheus Supercluster Cuts Training Interruptions by 99% Toward a Million GPUs
- Meta Reveals How Prometheus Will Scale to 1 Million GPUs
- Meta details Prometheus cluster scaling to roughly 1 million GPUs
- Meta Prometheus: Inside the Gigawatt Supercluster Scaling to 1 Million GPUs on GB200 and GB300 NVL72
(圖片來源:Meta)


本文地址:http://0o7.aukewel.com.cn/html/72a3799890.html
版权声明
本文仅代表作者观点,不代表本站立场。
本文系作者授权发表,未经许可,不得转载。